
Announcements
Running Data Agents with Tenki and Hotdata
Data agents need two things: somewhere safe to run code, and somewhere to keep and query data. Tenki gives them an isolated Linux sandbox, and Hotdata gives them a database they…
Why We Use LiquidCache
Hotdata's query engine is built on Apache DataFusion, and our tables are stored as Parquet. To keep repeated queries fast, we use LiquidCache, a cache for DataFusion that we…
Collecting Web Data into Hotdata with Bright Data
A lot of useful questions depend on data from the web, like product prices, reviews, or job listings. Bright Data is one of the most widely used ways to collect that data, with a…
Using Hotdata in RocketRide Pipelines
RocketRide is an open-source meta-harness for whole AI pipelines that helps teams build, debug, and deploy production AI workflows from their IDE. You design pipelines visually,…
Loading Data into Hotdata with dlt
dlt is an open-source Python library for building data pipelines. It takes care of pulling data from a source, figuring out the schema, and loading it in batches. Hotdata is now…
Giving LangChain Agents a Database with Hotdata
LangChain is a popular framework for building agents and chains on top of language models. With hotdata-langchain, a LangChain agent can work with Hotdata directly: it can run…
Querying Hotdata with Ibis
Ibis is a Python dataframe library that turns your expressions into SQL and runs them on a database. hotdata-ibis adds Hotdata as one of those databases. You write Ibis code in…
Benchmarking Concurrency on Hotdata, Snowflake and BigQuery
For AI applications, concurrency is one of the most important performance metrics. Agents tend to make many requests at the same time, and the slowest requests impact the entire…
ClickBench 10M: Hotdata vs Neon
We ran the ClickBench benchmark across 43 queries and 10 million rows (1.5 GB), comparing Hotdata to Neon.

Bringing DuckLake to Apache DataFusion
We've just released a new version of DuckLake + DataFusion and have donated it to the datafusion-contrib repository. We’re delighted to bring a new lakehouse catalog format to…
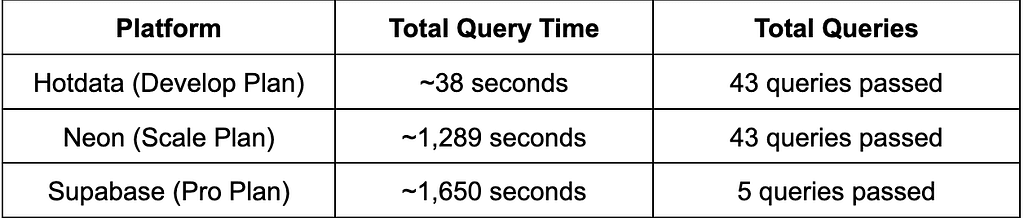
How Hotdata accelerates Neon and Supabase
Agents rarely connect to a single database. Transactional databases like Postgres generally store core application data, but agents often need to query multiple systems and…
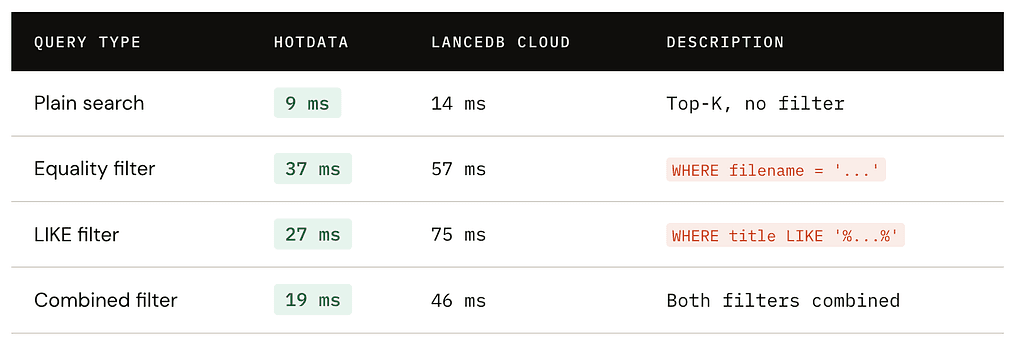
Building Vector Search Into a SQL Query Engine
We added native ANN search to our DataFusion-based engine using USearch, Parquet, and SQLite — with adaptive filtering and got impressive results.
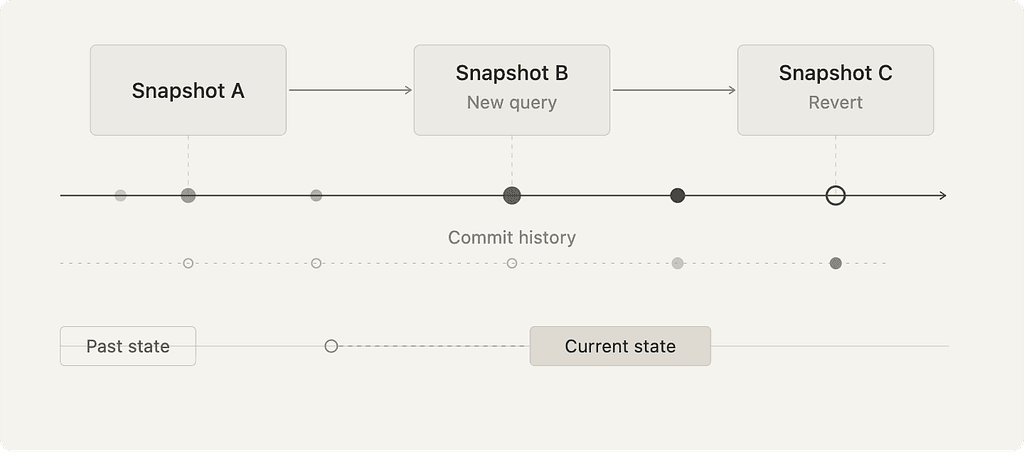
Why Agents Need Version Control for Data
In the early days, developers could keep knowledge of the systems they worked on in their heads. You changed a file, ran a test, and moved on. That worked when codebases were…
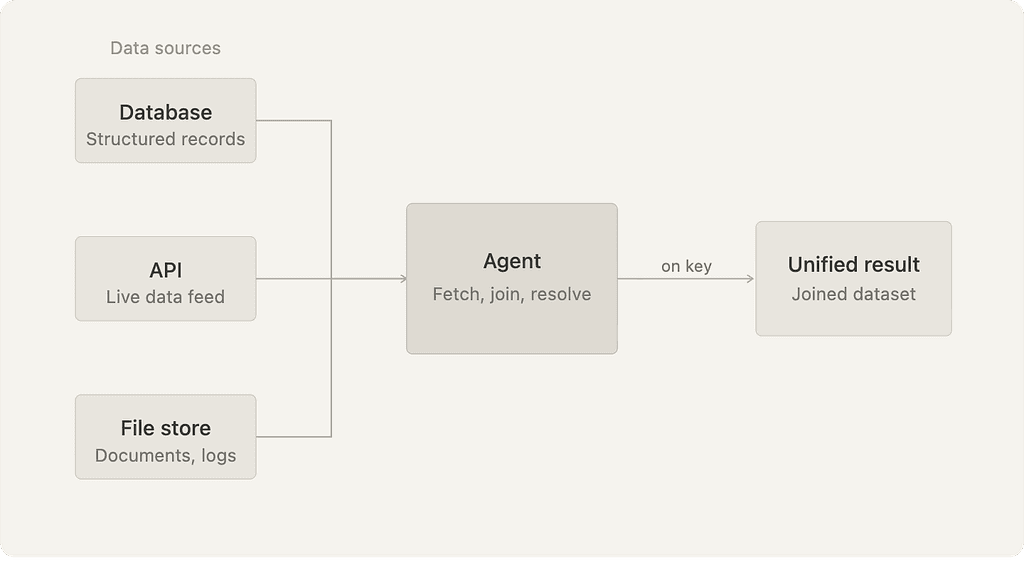
Agents Are Only as Good as the Data They Can JOIN
Now that everyone is building agents on diverse data sources and agents have better reasoning tools, how do you quickly assemble data from many different sources, in the right…
Query engines for Agents
We’re building a query engine, so I’ve been thinking about the difference between query engines built for humans and those specially made for agents. Regardless of the…
Why we are building Hotdata
Over the past decade, data infrastructure prioritized throughput and scale over latency and interactivity, cementing large distributed warehouses as the default.